Exact2Pass

The contemporary enterprise data center, high-performance computing (HPC), and artificial intelligence infrastructure landscape in 2026 demands ultra-low latency networking, lossless packet transport, and seamless orchestration across GPU compute clusters. As global organizations deploy large language models (LLMs), Retrieval-Augmented Generation (RAG) pipelines, and real-time inference engines, network architects and systems engineers must master the specialized physical and logical layers of AI-ready data centers. Earning the Cisco Certified Specialist - Data Center AI Infrastructure credential via the 300-640 DCAI examination validates your technical fluency in designing high-bandwidth fabrics, configuring Cisco UCS compute domains, tuning RoCEv2 protocols, and deploying orchestration tools like Cisco Hyperfabric, Nexus Dashboard, and Intersight. However, many data center engineers and infrastructure leads struggle on this 90-minute proctored assessment because they approach it as a standard network configuration exercise. Relying on flat review sheets or context-stripped question files found on unverified public forums cannot prepare you for the intricate situational logic of resolving Priority Flow Control (PFC) deadlocks, configuring Explicit Congestion Notification (ECN) marking thresholds, or tuning RDMA over Converged Ethernet (RoCEv2) parameters under intensive GPU cluster training loads.
True success on this scenario-driven technical evaluation requires a comprehensive, multi-dimensional command of both hardware acceleration topologies and fabric telemetry monitors. Infrastructure engineers must demonstrate sharp diagnostic judgment when evaluating NVLink GPU interconnects, configuring SAN/NVMe storage access policies, balancing power usage effectiveness (PUE) metrics, and managing hybrid cloud AI workloads. Candidates frequently spend several months searching for high-yield 300-640 exam questions online, hoping to locate an updated implementing cisco data center ai infrastructure study guide to evaluate their deployment readiness, or reviewing log files to verify telemetry alerts in Nexus Dashboard Insights. Without interactive workspace environments, a structured data center AI training course, or targeted practical simulator practice that can provide actual help in exam preparation, passive reading fails to build the diagnostic capabilities needed to handle buffer overrun drops or isolate latency spikes during distributed model training iterations.
At Exact2Pass, we replace passive reading with active, scenario-driven structural engineering exercises designed to build true platform confidence. Our premium preparation workspace simulates the functional operational layers, Cisco UCS Manager domain profiles, and real-time Nexus Dashboard fabric topology consoles of the active Cisco AI infrastructure ecosystem. We guide you through executing gap analyses on incoming AI cluster blueprints, configuring Enhanced Transmission Selection (ETS) bandwidth allocations, setting up vNIC QoS policies, and troubleshooting telemetry alerts across integrated compute and storage nodes. This focused practice builds the exact fabric-governance judgment and system deployment skills demanded by top-tier enterprise AI operations teams, ensuring you pass your official Pearson VUE proctored assessment on your very first try.
The 300-640 DCAI certification exam is engineered to evaluate your end-to-end AI workload analysis, lossless fabric configuration, compute domain orchestration, and operational telemetry capabilities across modern Cisco data center architectures. Our realistic simulation platform replicates active Cisco Intersight management panels, APIC fabric controllers, and real-time RoCEv2 performance monitoring displays instead of serving up generic multiple-choice items. You will master the underlying network congestion controls, operator-driven storage policies, and platform-level dependencies of the active Cisco framework, preparing you to tackle any scenario-based infrastructure question with ease.
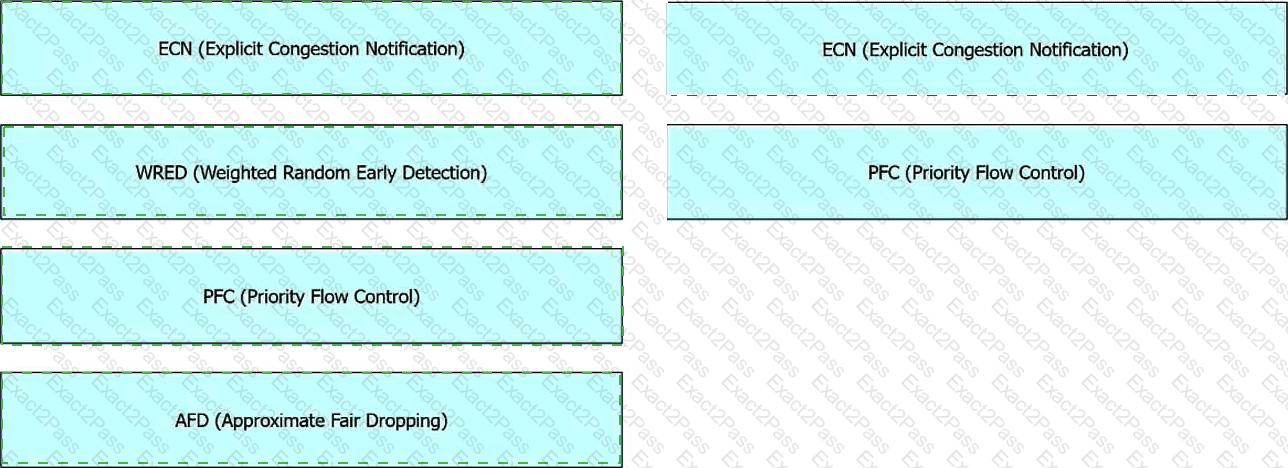
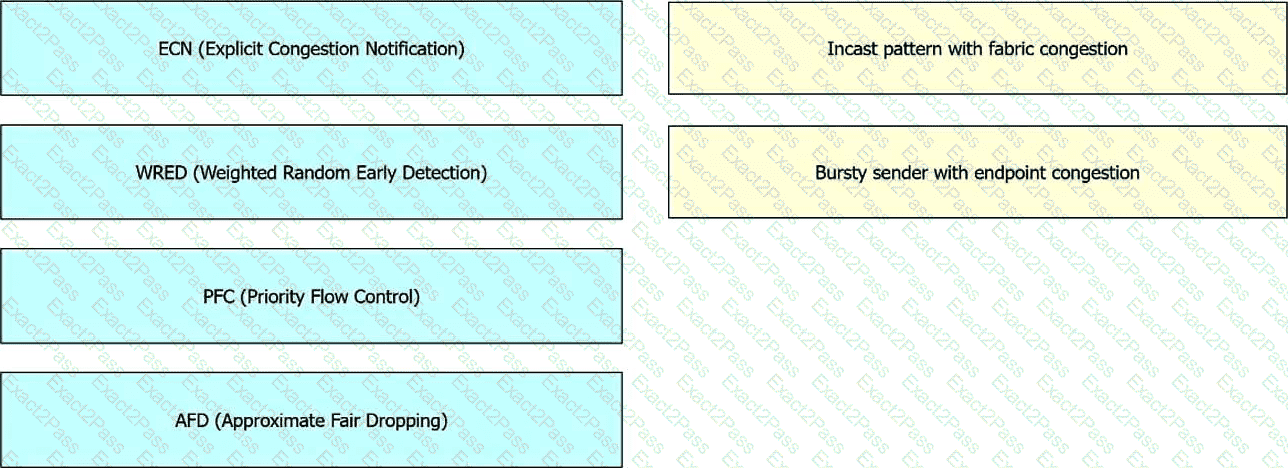
A network engineer is designing congestion management for an AI cluster using RoCEv2 transport. Based on Cisco best practices, the engineer must understand how ECN and PFC work together to provide lossless Ethernet transport.
Drag and drop the congestion management mechanisms from the left onto the corresponding descriptions on the right. Not all options are used.
What describes inference traffic patterns in AI deployments?
Refer to the exhibit.
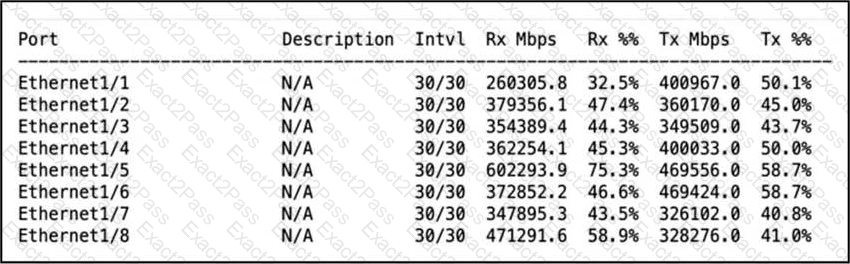
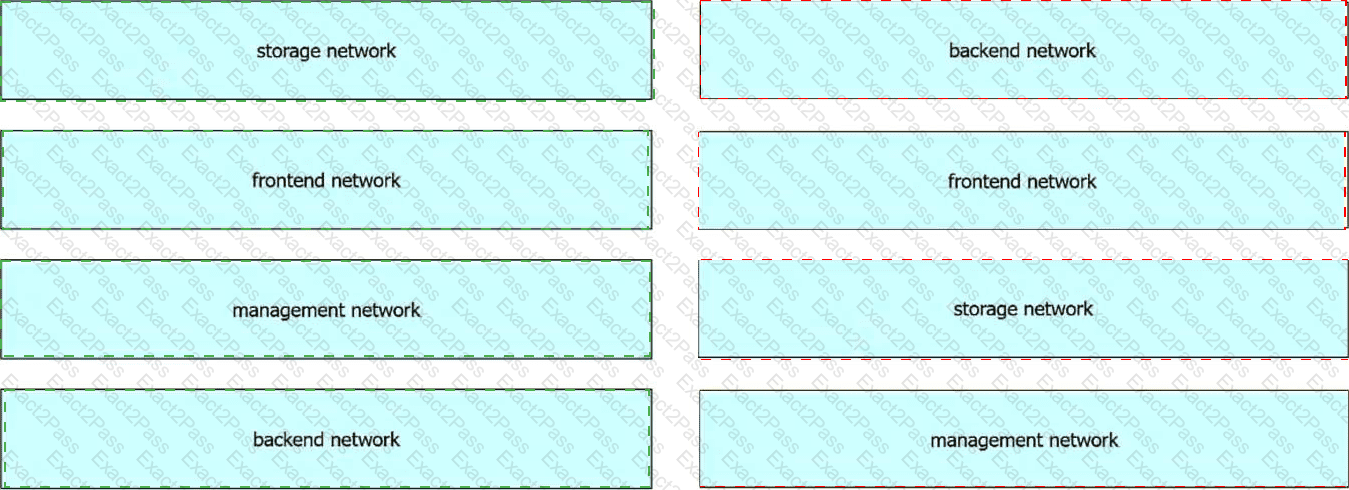
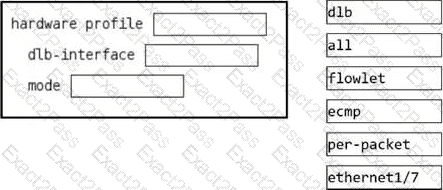
When a new AI backend network that supports Cisco UCS-based GPU servers with NVIDIA Connect-X network adapters is benchmarked, the traffic distribution observed has unacceptable variability across the interfaces.
Drag and drop the code snippets from the bottom onto the boxes in the code to configure the switch to resolve the issue.
A nationwide grocery chain has deployed Unified Edge to all its locations. Each store has 10 or more surveillance cameras that write approximately 1 Gb per hour. The surveillance retention policy requires maintaining 2 weeks of recording per camera.
Which type of cost-effective centralized storage solution must be evaluated with Unified Edge devices to adhere to this policy?
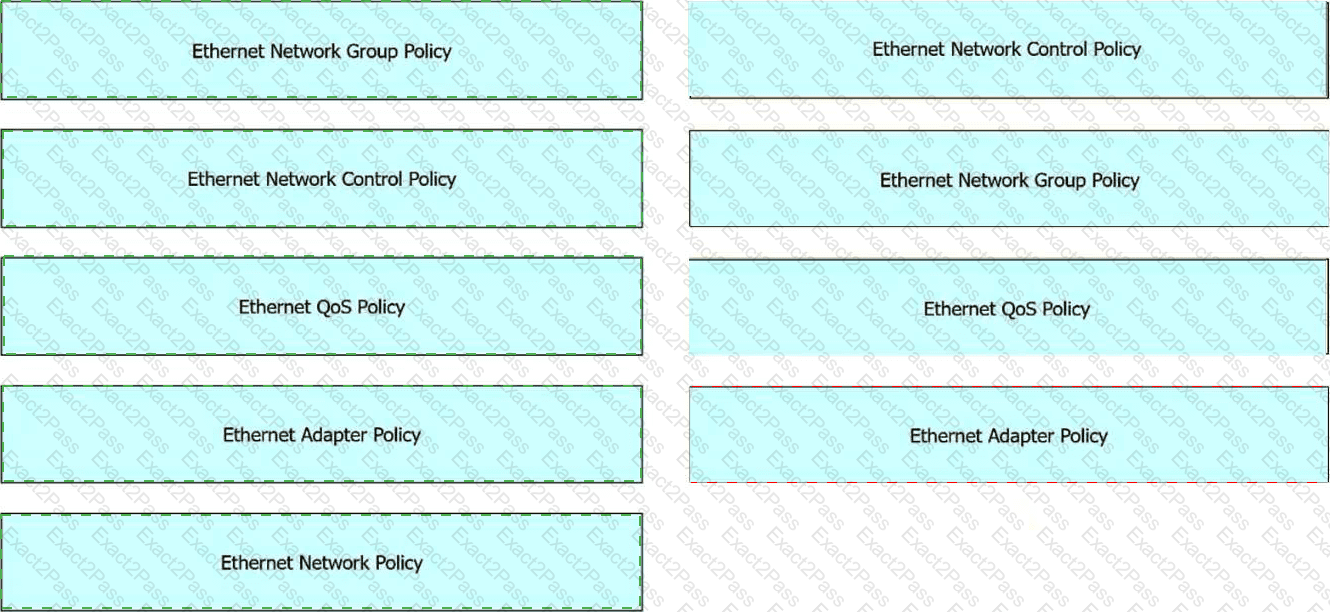
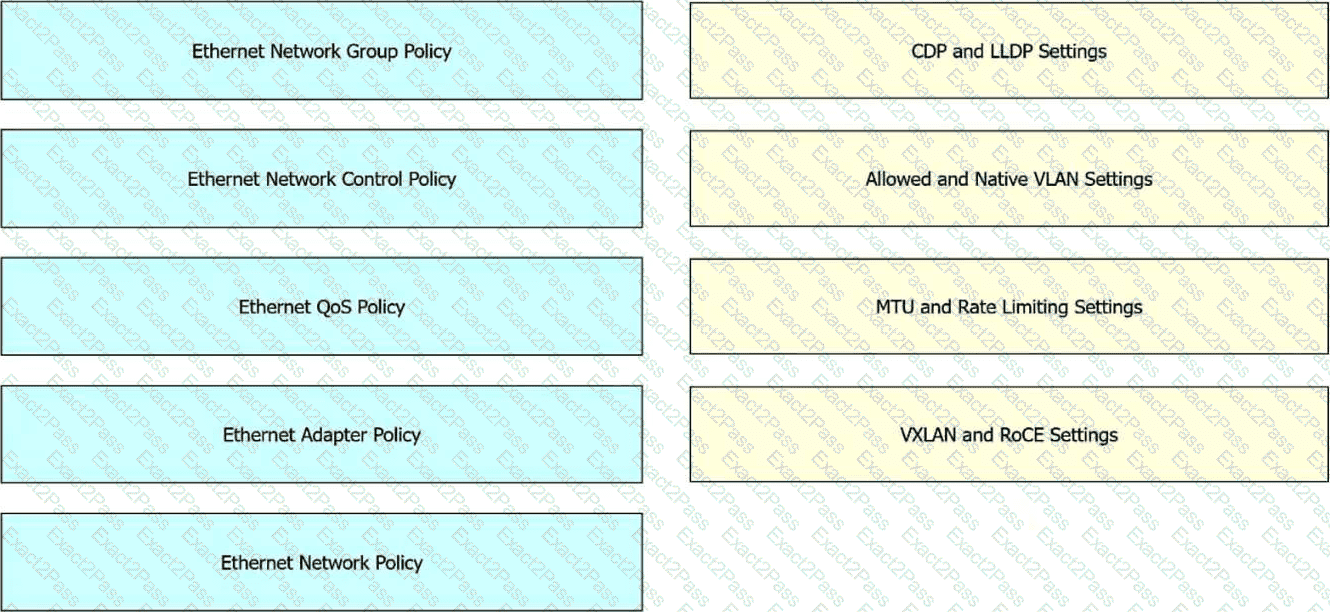
An engineer must configure vNIC templates for a UCS X-Series deployment.
Drag and drop the policy types from the left onto the corresponding configuration settings on the right. Not all options are used.
A network architect designs connectivity for a new Cisco AI POD operating in Intersight Managed Mode. To ensure high availability and aggregate bandwidth for external network traffic, a port channel must be established using multiple 100 GbE uplink ports on the fabric interconnects to connect to the upstream core switch infrastructure.
Which specific policy, applied through the domain profile, must be modified to define and configure this port channel on the fabric interconnects for the desired uplink connectivity?
A server administrator must monitor the performance and utilization of GPUs in Cisco UCS servers running AI workloads.
Which two metrics must be used in Cisco Intersight to accomplish these goals? (Choose two.)
Which components are part of the HyperFabric AI solution?